If you are searching for databricks competitors, you are usually trying to answer one practical question: what platform should your team evaluate instead of, or alongside, Databricks based on your main workload?
That workload may be SQL analytics, BI dashboards, ETL pipelines, streaming data, or machine learning. The challenge is that Databricks spans several categories at once, so the right alternative depends less on brand familiarity and more on what your team actually needs to do every day.
For BI managers, the real question is often whether Databricks is the right front-end analytics experience for business users. For data engineers, the question is whether a warehouse, ETL platform, or streaming engine would be simpler. For ML teams, it is whether you need a full lakehouse stack or a more specialized collaboration and modeling environment.
Quick Comparison Table
| Platform | Best for | Ease of use | BI / dashboarding | Data prep / ETL | Streaming | ML / AI workflows | Deployment style | Best-fit teams |
|---|---|---|---|---|---|---|---|---|
| FineBI | Business-friendly BI and self-service analytics | High for business users | Strong interactive dashboards and ad hoc analysis | Works with enterprise data sources but not an ETL-first platform | Depends on underlying data stack | Supports analytics consumption layer; not positioned as an ML platform | Enterprise deployment options | BI teams, business departments, enterprise analytics programs |
| Snowflake | SQL-first cloud analytics | High | Strong with partner BI tools | Good for ELT-centric workflows | Growing capabilities | Limited compared with Databricks for custom ML | Cloud managed | SQL-heavy analytics teams |
| Google BigQuery | Serverless analytics in GCP | High | Strong with BI ecosystem | Good for SQL transformations | Good ingestion ecosystem | BigQuery ML for SQL-centric ML use cases | Cloud serverless | GCP-centric analytics teams |
| Amazon Redshift | AWS-native data warehousing | Medium | Strong for BI workloads | Good in AWS data stacks | Moderate | Some ML-adjacent capabilities in AWS ecosystem | Managed cloud | AWS-first analytics teams |
| Fivetran | Low-maintenance data movement | High | Not a BI tool | Strong managed ELT connectors | Limited | Not an ML platform | SaaS | Lean data teams wanting managed ingestion |
| Informatica | Enterprise integration and governance | Medium | Not a BI-first platform | Strong enterprise ETL / data integration | Moderate | Supports enterprise data operations | Cloud / hybrid / enterprise | Large enterprises with governance-heavy integration needs |
| Talend | Data integration and quality | Medium | Not BI-first | Strong ETL / integration use cases | Moderate | Limited compared with ML platforms | Cloud / hybrid | Data integration teams |
| Confluent | Event streaming with Kafka ecosystem | Medium | Not a BI tool | Stream-oriented pipelines | Strong | Supports real-time data foundations | Cloud / self-managed ecosystem options | Real-time event-driven teams |
| Apache Flink-based platforms | Stateful stream processing | Medium to low | Not a BI tool | Advanced stream processing | Strong | Can support ML pipelines indirectly | Managed or self-managed | Engineering teams with real-time processing needs |
| RisingWave | Streaming SQL analytics | Medium | Analytics-oriented for streaming use cases | Stream transformations | Strong | Limited ML focus | Cloud-native / modern streaming stack | Teams building real-time SQL analytics |
| Snowpark-based stacks | SQL + Python data apps in Snowflake environments | Medium | Strong when paired with BI layer | Good for in-platform transformations | Moderate | Better for teams standardizing in Snowflake ecosystem | Cloud managed | Snowflake-centered data and app teams |
| Microsoft Fabric | Unified Microsoft analytics experience | Medium to high | Strong with Power BI integration | Broad data workflow coverage | Growing | Broad AI and analytics positioning | Cloud SaaS | Microsoft-centric enterprises |
This table is intentionally broad because Databricks competes across multiple layers. A warehouse may replace part of it. An ETL tool may replace another part. A BI platform may solve the business-facing analytics gap even if Databricks remains in the data backend.
Databricks competitors in 2026 at a glance
Databricks is commonly evaluated against cloud warehouses, ETL platforms, streaming platforms, and ML environments because it combines data engineering, analytics, and AI workflows in one lakehouse-style platform. That breadth is its strength, but it also means not every organization needs the whole package.
What this comparison covers across BI, ETL, streaming, and ML
This guide compares 12 Databricks competitors across four practical buying categories:
- BI and analytics platforms
- ETL and data integration platforms
- Streaming and event data platforms
- ML and unified data platforms
The goal is not to declare one universal winner. The goal is to help you shortlist tools based on:
- your dominant workload
- your team’s skill level
- operational complexity
- governance requirements
- cost predictability
- time to value
How the 12 alternatives were selected and grouped by primary use case
The alternatives below were selected because they are commonly considered when organizations evaluate Databricks for one of these reasons:
- They want simpler SQL analytics
- They need easier self-service BI
- They prefer managed ETL / ELT
- They need dedicated streaming infrastructure
- They want a more focused ML collaboration environment
- They are standardizing on a cloud ecosystem such as AWS, Azure, or GCP
Quick summary of which teams should shortlist each platform first
Here is the short version:
- Shortlist FineBI first if your main problem is business-facing analytics, self-service dashboards, governed reporting, and adoption by non-technical users.
- Shortlist Snowflake, BigQuery, or Redshift if your organization is primarily solving SQL analytics and warehouse performance.
- Shortlist Fivetran, Informatica, or Talend if your bottleneck is pipeline development, connector maintenance, or enterprise integration.
- Shortlist Confluent, Flink-based platforms, or RisingWave if low-latency event processing is central.
- Shortlist Snowpark-based stacks or Microsoft Fabric if you need broader analytics and AI collaboration outside a Spark-first experience.
How to compare alternatives by use case
A common mistake in Databricks evaluations is comparing every tool as if it should do everything. It is more useful to compare by primary workload first.
For BI and analytics teams
If you are a BI leader, analytics manager, or reporting team, do not start by asking which platform has the most impressive architecture. Start by asking whether business users can actually get answers quickly.
Evaluate dashboarding, semantic modeling, ad hoc querying, and governance
For analytics teams, the important evaluation points usually include:
- Can business users build or modify dashboards without engineering help?
- Is there a governed semantic layer or metric logic you can standardize?
- How easy is ad hoc analysis for finance, sales, operations, and regional teams?
- Can dashboards be shared, filtered, drilled into, and reused consistently?
- How strong are permissions and enterprise governance controls?
Databricks can support analytics workflows, especially for technical teams, but some organizations still add a dedicated BI layer because business adoption requires a more intuitive front-end.
Check warehouse performance, concurrency, and cost predictability
If your BI workloads are query-heavy, compare:
- concurrent dashboard performance
- data freshness expectations
- cost variability under heavy analyst usage
- separation of storage and compute
- workload isolation for business reporting vs engineering jobs
For ETL and data engineering teams
Engineering teams should compare platforms based on pipeline reliability and operational overhead, not on dashboard screenshots.
Compare pipeline orchestration, transformations, connectors, and reliability
Key questions include:
- How much connector maintenance is required?
- Are transformations SQL-first, code-first, or mixed?
- How are failures, retries, scheduling, and dependencies managed?
- Does the tool support batch, micro-batch, or both?
- How much engineering effort is needed to keep pipelines healthy?
Review developer experience, observability, and deployment flexibility
Also compare:
- notebook vs IDE workflows
- version control friendliness
- testing support
- observability and alerting
- cloud-only vs hybrid deployment needs
For streaming and real-time workloads
If your core use case is event-driven data, you need to compare streaming platforms differently from batch analytics tools.
Assess event ingestion, latency, stateful processing, and scaling behavior
Review:
- ingestion throughput
- end-to-end latency
- stateful processing support
- fault tolerance and recovery behavior
- scaling consistency under spikes
Consider ecosystem fit for Kafka, CDC, and real-time analytics
Real-time architecture decisions usually depend on:
- Kafka or Kafka-compatible ecosystems
- CDC requirements
- SQL on streams vs code-first stream processing
- downstream dashboard or alerting integration
- whether you need operational analytics or analytical serving
For ML and AI workloads
Databricks is often strongest in organizations where notebooks, distributed processing, and collaborative ML are central. But it is not the only option.
Compare notebook workflows, experiment tracking, feature engineering, and model deployment
Compare these areas:
- notebook usability and collaboration
- experiment tracking
- feature engineering workflows
- model registry and deployment support
- handoff between data engineering and data science
Look at support for Python ecosystems, MLOps, and collaboration
Also evaluate:
- Python-native workflow support
- integration with broader MLOps tooling
- reproducibility
- security and governance for ML artifacts
- cross-functional collaboration between analysts, engineers, and data scientists
12 alternatives compared by category
Cloud data warehouse and analytics platforms
1. FineBI
Website: https://www.fanruan.com/en/finebi
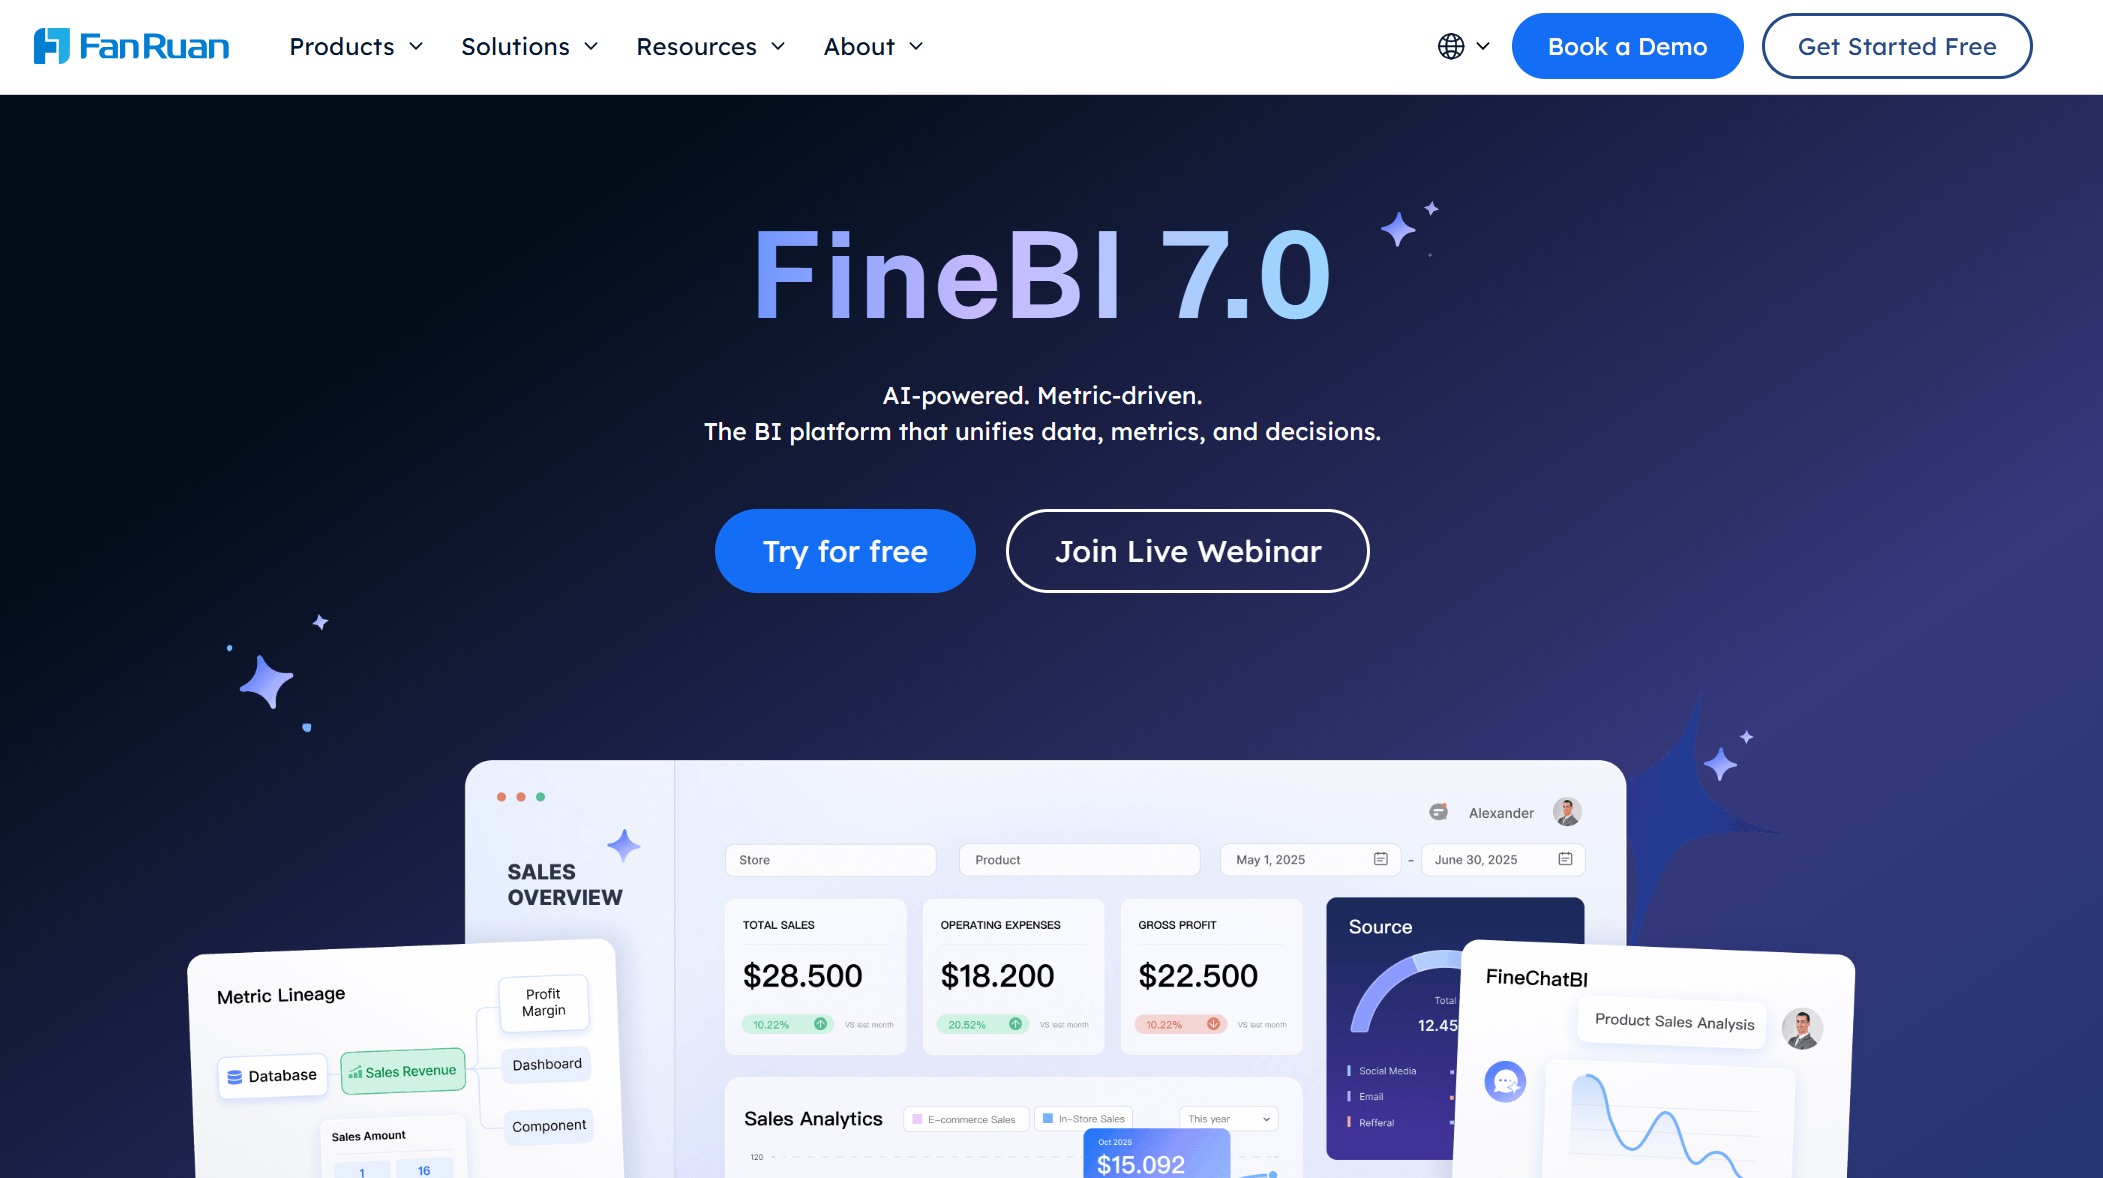
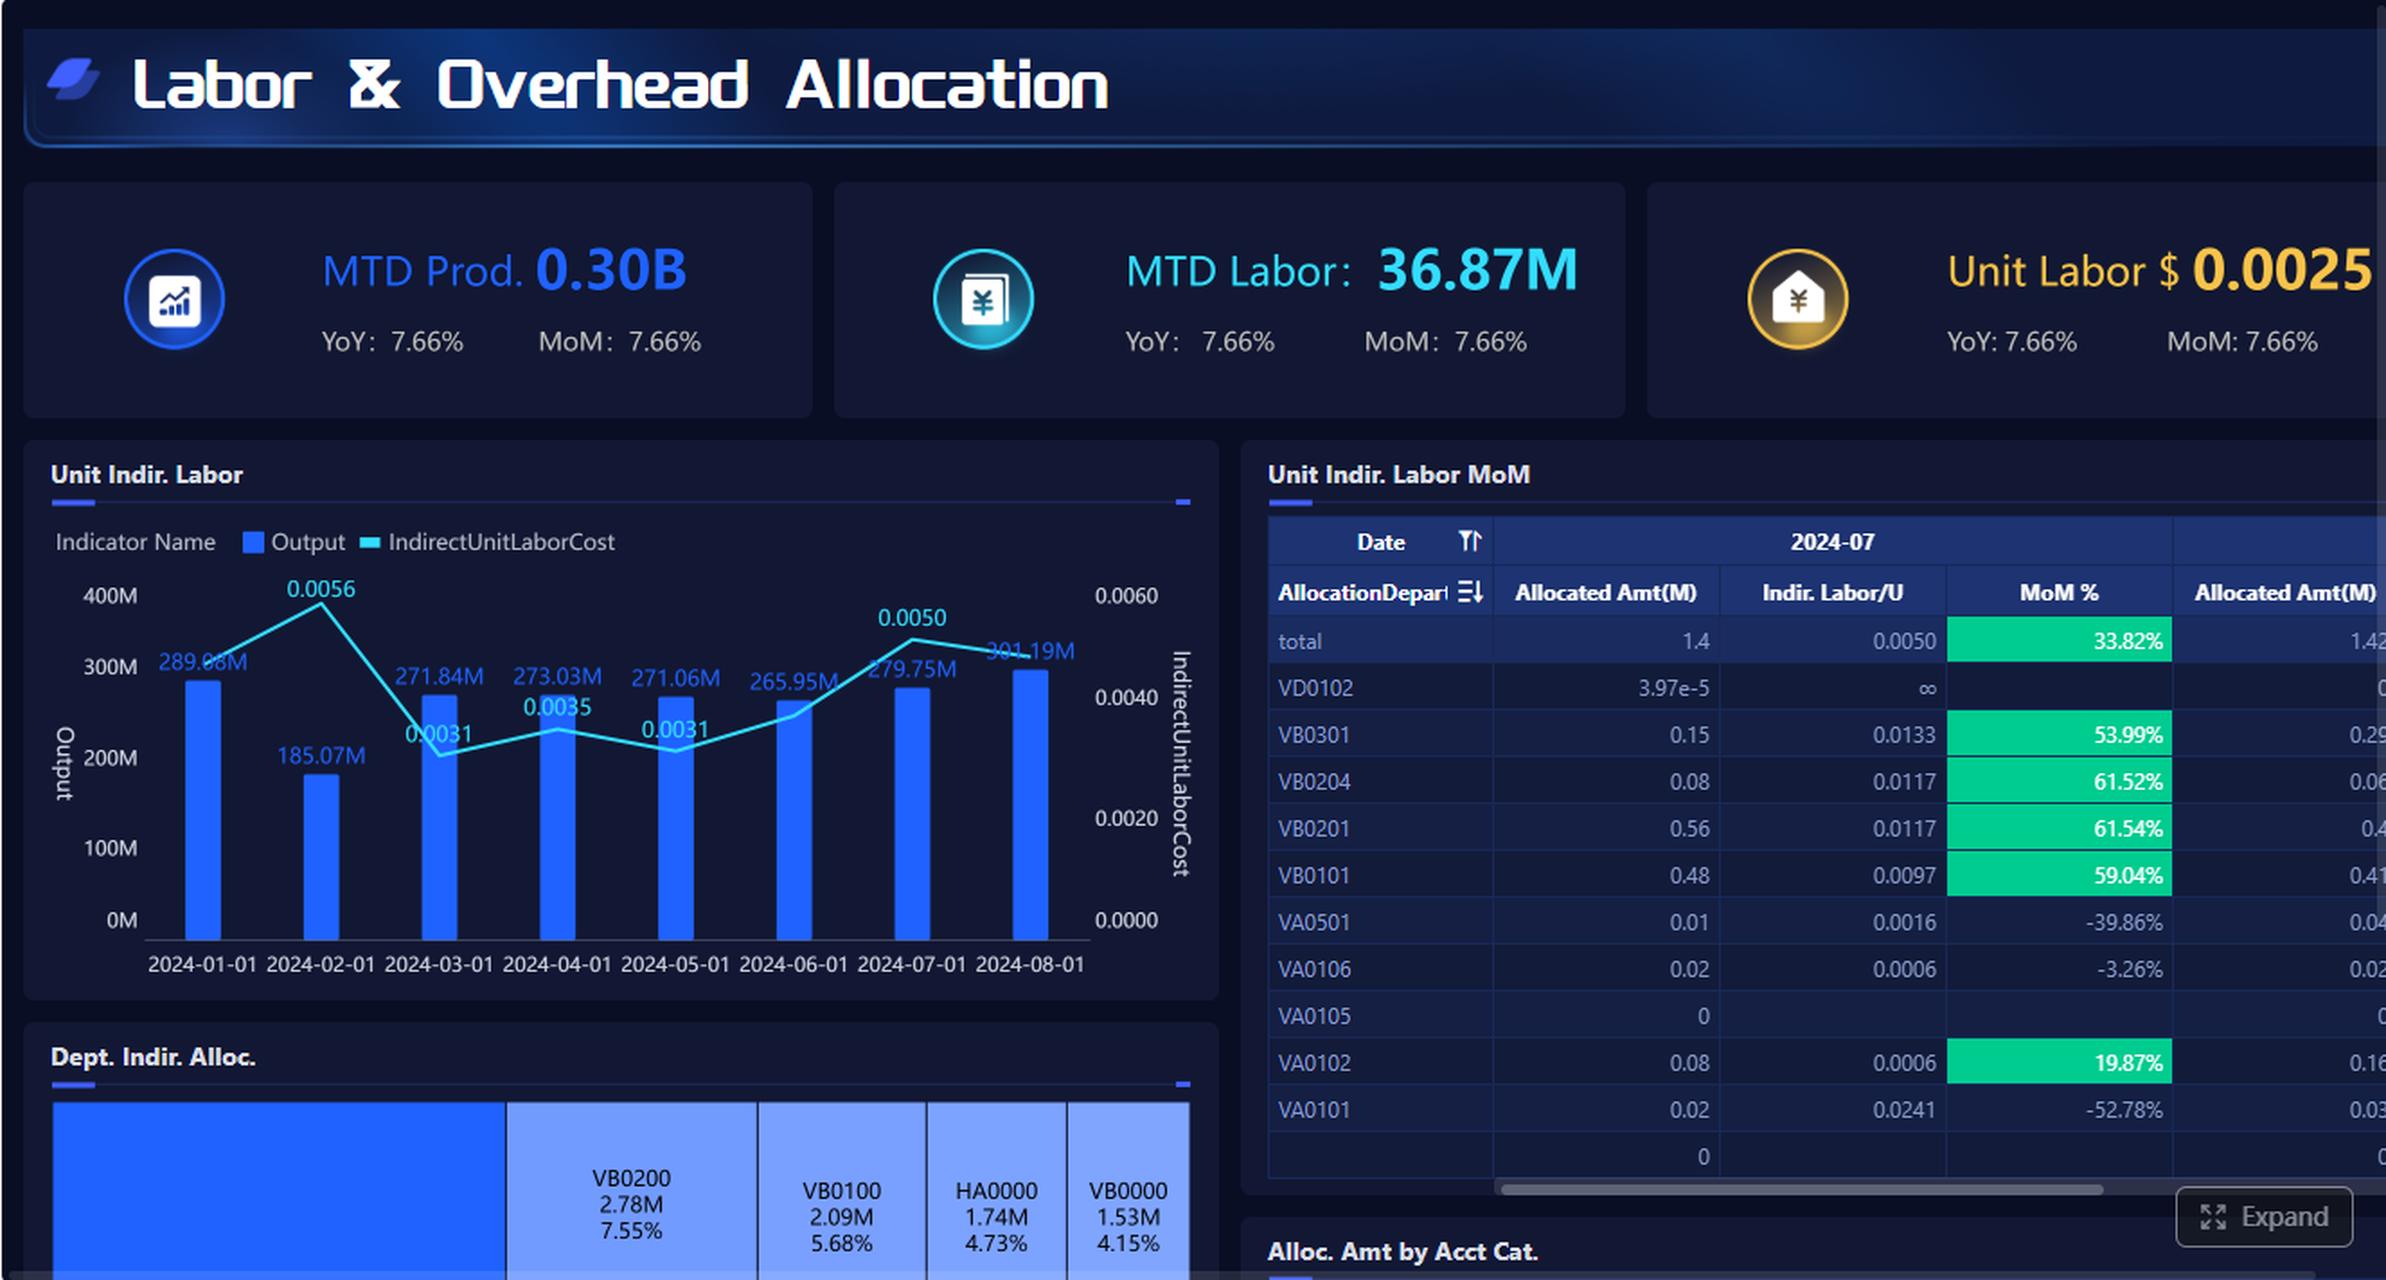
Although FineBI is not a direct lakehouse replacement, it deserves a place at the top of a Databricks competitors shortlist when the evaluation is really about analytics delivery and business-user adoption rather than backend compute alone.
FineBI is positioned as a self-service BI and analytics platform for enterprises that need governed dashboards, interactive analysis, and easier access to data for business teams. In many organizations, Databricks handles storage, transformation, or engineering workloads, while FineBI becomes the front-end layer that turns trusted data into dashboards and exploration workflows people actually use.
Where FineBI is most relevant:
- Business departments need drag-and-drop dashboard creation
- Analysts need interactive exploration and drill-down
- Enterprises need governed metrics and dashboard sharing
- Teams want faster iteration than code-heavy analytics workflows
- BI adoption matters beyond engineers and data scientists
FineBI is especially practical for organizations that have strong backend data infrastructure but still struggle with dashboard standardization, self-service adoption, or business accessibility.
Its strengths commonly include:
- self-service BI for business users
- interactive dashboards and visual analysis
- drag-and-drop analytics experience
- drill-down and cross-analysis
- enterprise data connectivity
- dashboard sharing and collaboration
- support for governed enterprise reporting scenarios
Trade-offs to understand clearly:
- FineBI is not positioned as a full replacement for Databricks in data engineering, distributed Spark processing, or advanced ML workloads
- It is most valuable as the analytics and consumption layer
- Teams still need a trusted data foundation underneath, whether from a warehouse, lakehouse, or other enterprise data platform
For many enterprises, that is exactly the right split: use backend platforms for heavy data processing, and use FineBI to make data usable across the business.
2. Snowflake
 Website: https://www.snowflake.com/
Snowflake is one of the most common Databricks alternatives for organizations focused on SQL analytics and cloud data warehousing.
It is often preferred by teams that want:
- strong performance for concurrent BI workloads
- managed operations
- SQL-first adoption
- workload isolation through independent compute
- easier onboarding for analytics teams
Snowflake is typically a better fit than Databricks when the main priority is scalable analytics on structured and semi-structured data rather than Spark-centric engineering and custom ML workflows.
Trade-offs:
- less centered on notebook-first engineering
- often supplemented with external ETL, orchestration, or BI tools
- may not be the first choice for highly customized ML pipelines
3. Google BigQuery
 Website: https://cloud.google.com/bigquery
BigQuery is a strong option for teams that prioritize serverless analytics and are already invested in Google Cloud.
It appeals to teams that want:
- minimal infrastructure management
- large-scale SQL analytics
- rapid querying of large datasets
- strong fit with Google Cloud services
- streamlined access for analysts
It is often shortlisted against Databricks when teams want to reduce operational complexity and focus more on analytics than on engineering customization.
Trade-offs:
- cost predictability can depend on usage patterns
- less suitable for teams wanting deep Spark-style engineering workflows
- often paired with external BI and transformation tools
4. Amazon Redshift
 Website: https://aws.amazon.com/redshift/
Redshift remains a common choice for AWS-centered organizations looking for a managed warehouse instead of a broader lakehouse environment.
It is a strong candidate when teams want:
- native alignment with AWS ecosystem services
- established SQL analytics patterns
- high concurrency for BI reporting
- tighter warehouse-centered operations
Trade-offs:
- narrower scope than Databricks for engineering and ML-heavy scenarios
- often requires complementary tools for broader data platform workflows
ETL and integration platforms
5. Fivetran
 Website: https://www.fivetran.com/
Fivetran is not a Databricks replacement in the broad platform sense, but it is a frequent alternative when the real problem is simply reliable data ingestion and ELT.
It is ideal for teams that want:
- managed connectors
- low-maintenance pipeline operations
- fast time to value
- minimal engineering resources for ingestion
Fivetran is most relevant when organizations do not need Databricks for complex engineering and instead need dependable movement of SaaS and database data into a warehouse.
Trade-offs:
- not a BI platform
- not a full transformation environment on its own
- not designed for custom streaming or ML workloads
6. Informatica
 Website: https://www.informatica.com/
Informatica is often considered by large enterprises with complex governance and integration requirements.
Best-fit scenarios include:
- enterprise-grade data integration programs
- regulated industries
- hybrid environments
- data quality and master-data-oriented initiatives
Compared with Databricks, Informatica may feel more structured and enterprise integration-centric, especially for organizations prioritizing governance and established enterprise data practices.
Trade-offs:
- can be heavier to implement
- may feel less flexible for code-centric engineering teams
- not a business-user BI platform
7. Talend
 Website: https://www.qlik.com/us/qlik-talend
Talend is commonly evaluated for data integration, transformation, and quality-oriented workloads.
It can be attractive when teams need:
- broad integration capabilities
- ETL and data movement workflows
- support for mixed data environments
- practical transformation tooling
Trade-offs:
- not a direct alternative for interactive BI consumption
- not a specialized streaming-first platform
- not as unified for notebook-based ML work as Databricks
Streaming and event data platforms
8. Confluent
 Website: https://www.confluent.io/
Confluent is a leading shortlist option when the requirement is real-time event streaming, especially in Kafka-centered architectures.
It is well suited for:
- event-driven pipelines
- streaming integration
- operational event backbones
- CDC-driven architectures
- real-time analytics foundations
Compared with Databricks, Confluent is more specialized around streaming infrastructure rather than broad warehouse, BI, and ML workflows.
Trade-offs:
- not a complete BI or warehouse solution
- generally part of a wider data stack rather than the entire platform
9. Apache Flink-based platforms
Website: https://flink.apache.org/
Flink-based platforms are strong candidates when you need stateful stream processing and sophisticated real-time data transformations.
Best-fit scenarios include:
- low-latency stream processing
- complex event handling
- real-time aggregations and anomaly detection
- engineering-led streaming architectures
Trade-offs:
- steeper learning curve for many teams
- not intended as a business-friendly BI layer
- usually requires more architecture planning than managed analytics platforms
10. RisingWave
 Website: https://risingwave.com/
RisingWave is relevant for teams interested in streaming SQL analytics and modern real-time analytical workloads.
It can be attractive where teams want:
- SQL-friendly streaming access
- incremental processing
- lower-latency analytical use cases
- modern event-driven analytics patterns
Trade-offs:
- more specialized than Databricks
- narrower ecosystem maturity than more established categories
- not designed to be a complete enterprise BI platform alone
ML and unified data platforms
11. Snowpark-based stacks
 Website: https://www.snowflake.com/en/product/features/snowpark/
Snowpark-based stacks are increasingly considered by teams standardizing on Snowflake but wanting broader development flexibility for data applications and transformations.
These stacks are relevant when organizations want:
- to stay within the Snowflake ecosystem
- to support more than pure SQL workflows
- closer alignment between warehouse logic and application logic
- an alternative to moving into Spark-heavy environments
Trade-offs:
- best suited to organizations already committed to Snowflake
- ML and advanced engineering breadth still depends on surrounding tools and architecture
Microsoft Fabric
 Website: https://www.microsoft.com/en-us/microsoft-fabric
Microsoft Fabric is commonly evaluated by organizations already invested in Microsoft’s data and analytics ecosystem.
It is relevant when teams want:
- tighter alignment with Microsoft analytics workflows
- a more unified SaaS experience
- strong integration with Power BI
- consolidated analytics capabilities under one ecosystem
Trade-offs:
- best fit is often strongest for Microsoft-centric environments
- long-term suitability depends on how deeply your team wants to align with that ecosystem
Strengths, trade-offs, and best-fit scenarios
Where Databricks may be stronger
Databricks remains especially strong where organizations want a unified environment for:
- engineering, analytics, and ML workflows
- large-scale Spark-based processing
- notebook-centric collaboration
- lakehouse architectures
- advanced transformation and ML experimentation in one place
For technical teams that actively use distributed compute, notebooks, and multi-stage data workflows, Databricks can provide significant breadth.
Where competitors may be a better fit
Competitors may be a better choice when your organization values:
- faster time to value for a narrower use case
- simpler operations
- lower learning curve for SQL or business users
- specialized streaming infrastructure
- ETL-first reliability
- stronger business-facing dashboard adoption
- more predictable warehouse-centered usage patterns
A practical example: if your executives and department managers mostly need governed dashboards and self-service slicing of trusted data, a dedicated BI layer like FineBI may create more business value than expanding a technical platform alone.
Best choices by team profile
Best for SQL-heavy analytics organizations
Consider:
- Snowflake
- Google BigQuery
- Amazon Redshift
- Microsoft Fabric in Microsoft-centric environments
If business teams also need stronger self-service consumption, add FineBI as the analytics layer.
Best for low-maintenance ETL and ELT operations
Consider:
- Fivetran
- Informatica
- Talend
These are especially relevant if your main pain is data movement and operational pipeline maintenance.
Best for real-time event processing and streaming pipelines
Consider:
- Confluent
- Apache Flink-based platforms
- RisingWave
These are better suited than a general analytics platform when streaming is the primary requirement.
Best for collaborative ML and applied AI teams
Consider:
- Databricks for Spark-heavy and notebook-centered workflows
- Snowpark-based approaches if your organization is already standardized on Snowflake
How to choose the right platform in 2026
Decision checklist before you migrate or buy
Before selecting from these Databricks competitors, validate the following.
Primary workload: BI, ETL, streaming, ML, or a mix
Identify your dominant workload first:
- If it is BI, shortlist FineBI plus your preferred data platform
- If it is ETL, shortlist Fivetran, Informatica, or Talend
- If it is streaming, shortlist Confluent, Flink-based platforms, or RisingWave
- If it is ML, compare Databricks, and ecosystem-native options
- If it is a mix, decide which workload matters most operationally
Team skills, governance needs, and integration requirements
Then ask:
- Are your users mostly engineers, analysts, or business users?
- Do you need strict metric governance?
- Do you need hybrid deployment or enterprise controls?
- How important is low-code access?
- How many existing systems must connect cleanly?
Budget model, scaling expectations, and lock-in concerns
Finally, compare:
- warehouse vs platform vs connector cost models
- variable usage risk
- growth in data volume and concurrency
- ecosystem dependence
- switching costs over time
Final recommendation framework
Choose by your dominant use case first, then validate multi-workload fit
A sound buying framework is:
- Identify the workload that creates the most cost or delivery pressure today.
- Choose the platform category that best solves that workload.
- Validate whether it can support adjacent workloads well enough.
- Avoid overbuying a broad platform if your actual need is narrow and urgent.
Run a proof of concept with representative data, latency, and cost targets
Do not rely only on demos. Run a proof of concept with:
- realistic data volumes
- representative joins and transformations
- dashboard concurrency requirements
- expected latency thresholds
- governance and access rules
- target budget guardrails
Practical recommendations for shortlisting Databricks competitors
Here are five recommendations I would give any enterprise evaluating alternatives.
-
Separate the backend question from the analytics adoption question.
Many teams compare platforms only at the data infrastructure level and ignore whether business users can actually consume insights easily. -
Score each tool against one primary success metric.
For example: fastest dashboard delivery, lowest ETL maintenance, lowest streaming latency, or strongest ML collaboration. -
Test with your real user mix.
A platform that works for engineers may fail with finance or operations users. Include business stakeholders in evaluations. -
Model operational overhead, not just feature breadth.
A broader platform is not always the cheaper or faster option once staffing, support, and governance are included. -
Plan the architecture as a stack, not a single product bet.
In practice, many enterprises use a warehouse or lakehouse for data processing, then add a BI layer for analytics delivery and an AI layer for actionability.
When FineBI + Dora is a smart alternative in the Databricks conversation
Tools like Databricks, Snowflake, BigQuery, and Microsoft Fabric are widely used across the modern data platform market. But teams that need a more business-user-friendly, self-service BI platform may also consider FineBI as a practical analytics layer, especially when the challenge is dashboard adoption, governed exploration, and faster business response.
FineBI fits well when you need to:
- deliver dashboards to business departments quickly
- reduce dependence on technical teams for every analytical question
- support drag-and-drop analysis and drill-down
- standardize KPIs and sharing across teams
- connect trusted enterprise data into a governed dashboard experience
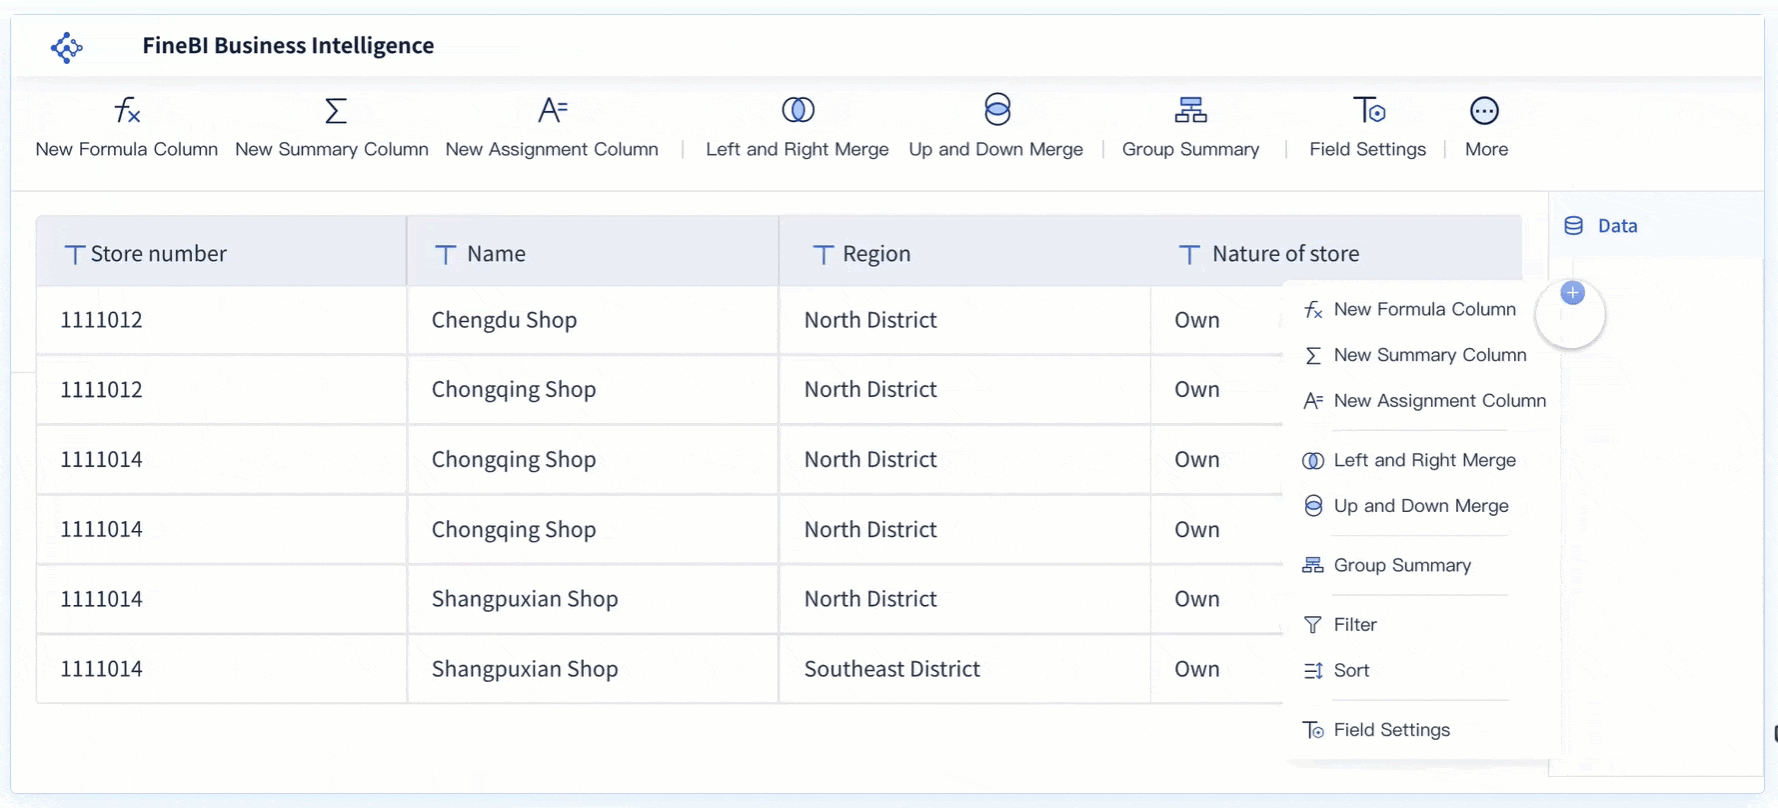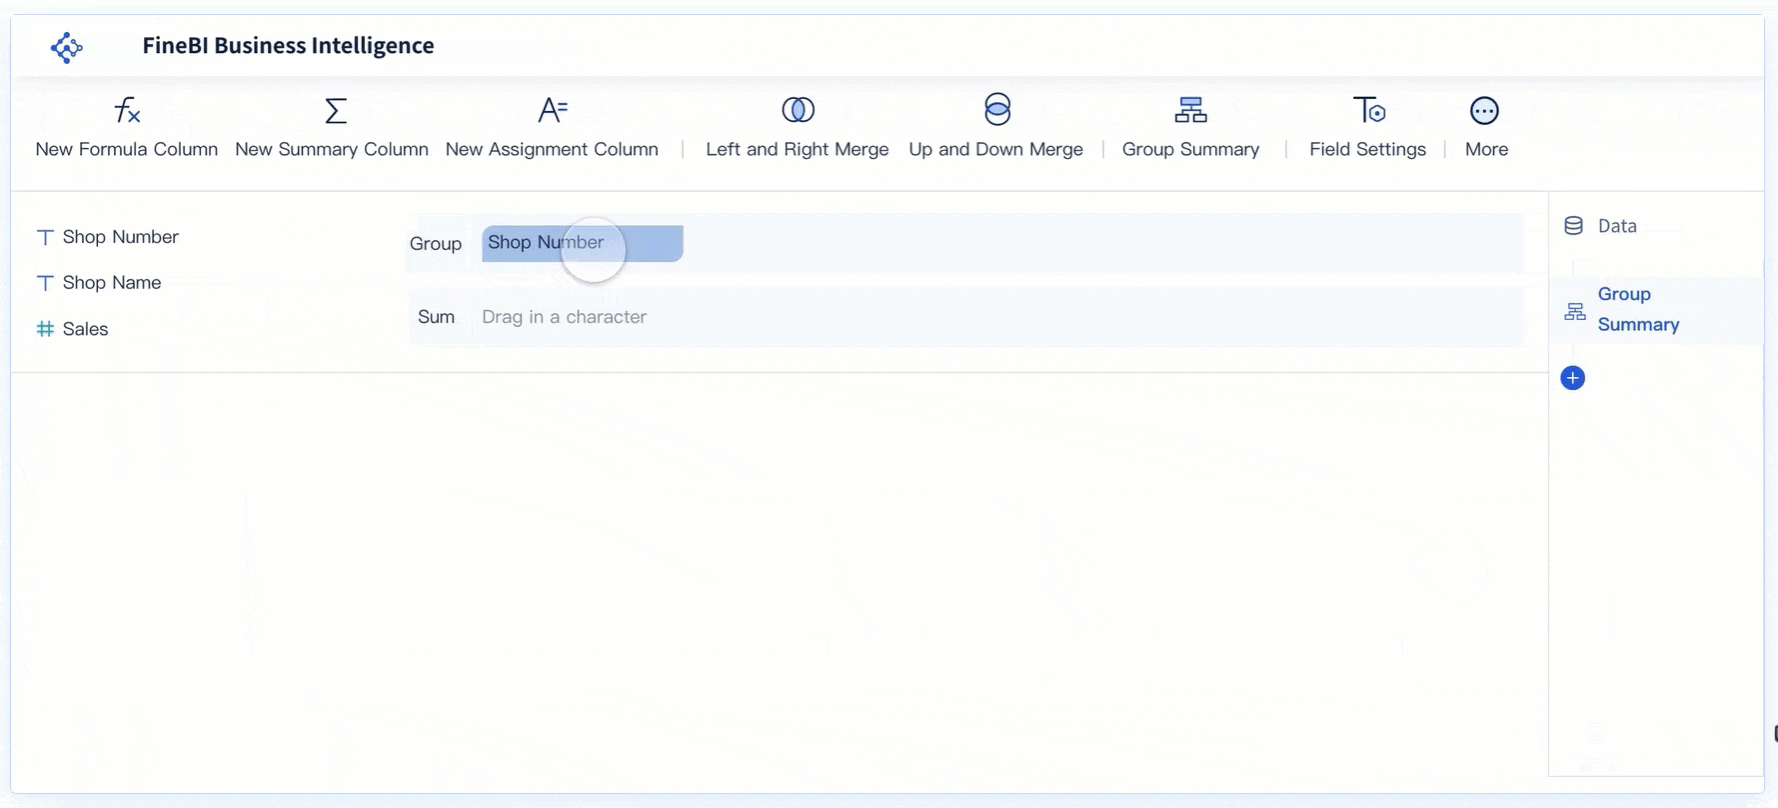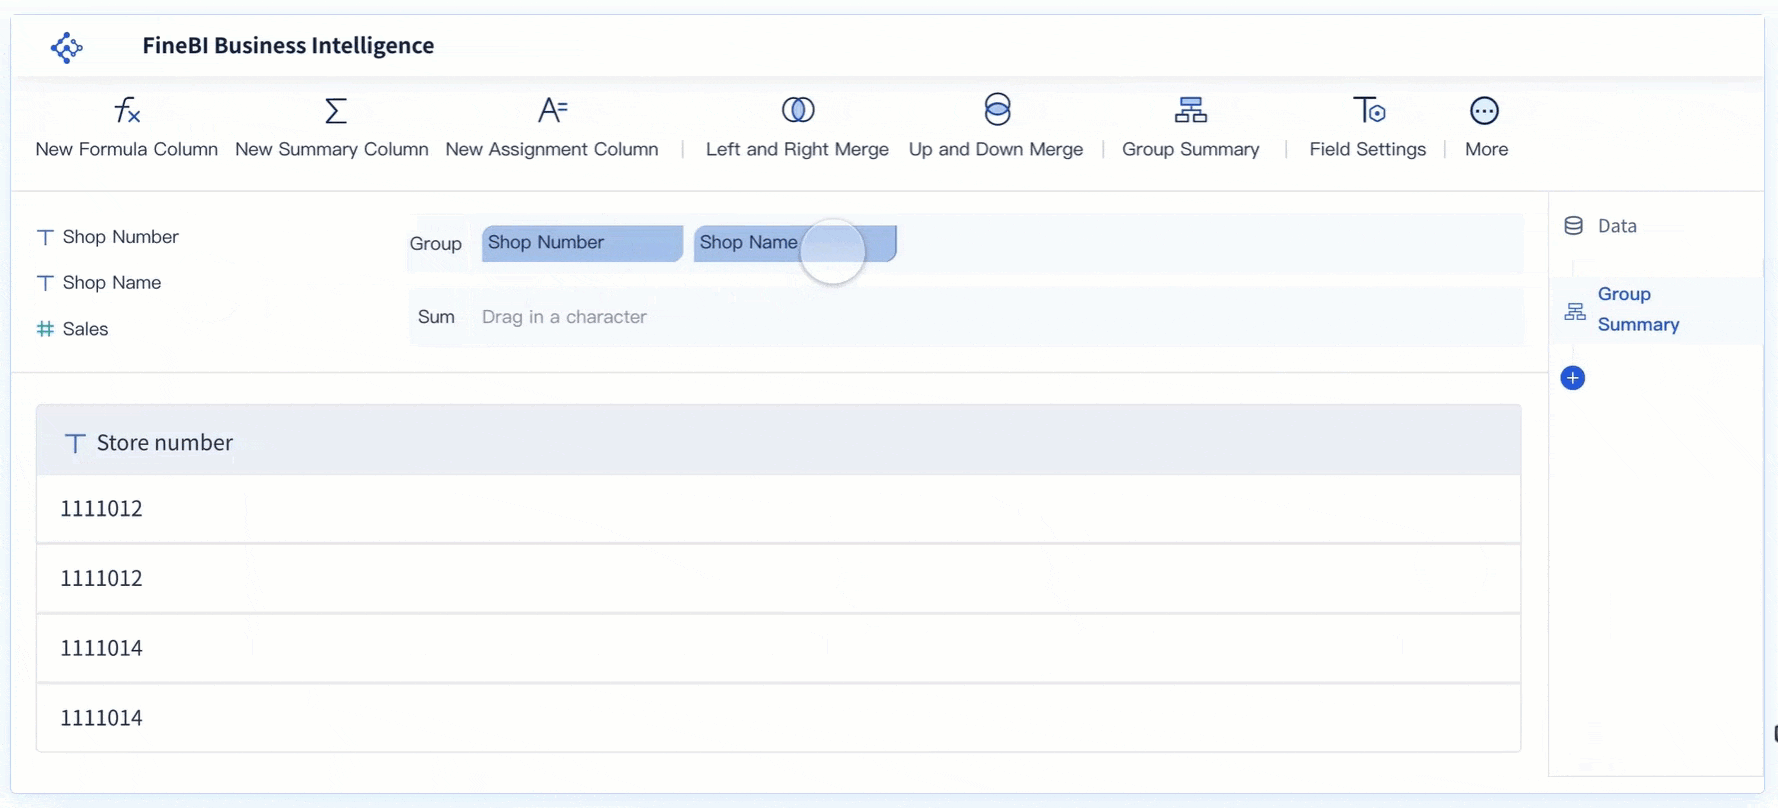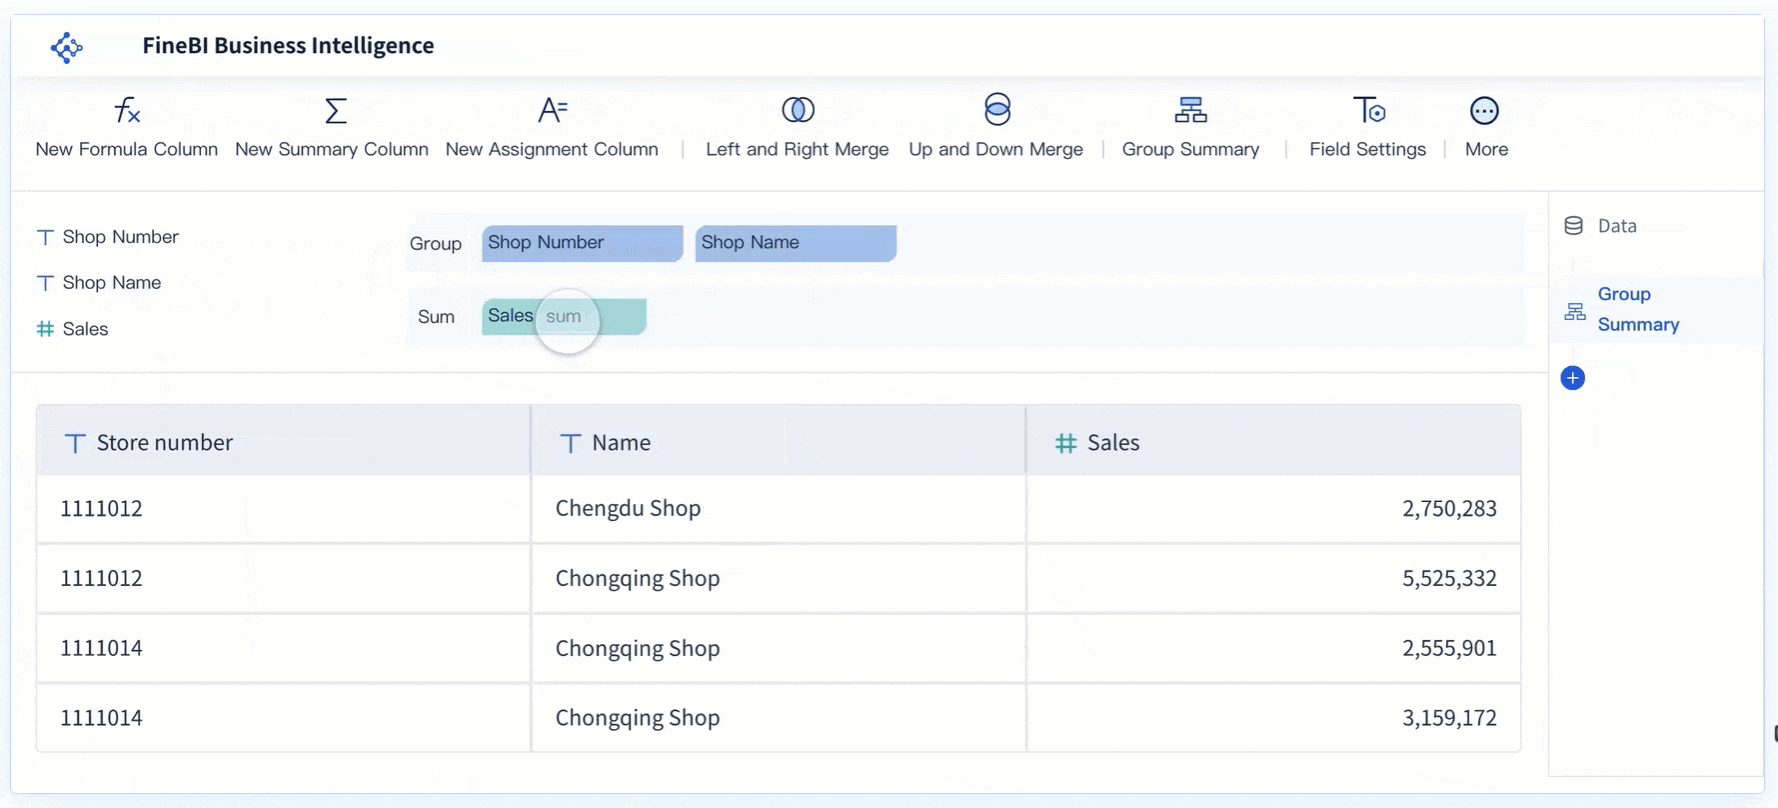 Drag-and-drop Analysis
This is where FineBI + Dora becomes especially relevant.
FineBI provides the trusted dashboard, metric, and semantic foundation. Dora is FanRuan’s enterprise Data Agent platform that adds an AI assistant layer on top of FineBI and existing enterprise data assets.
Together, FineBI + Dora helps organizations move from:
- people manually checking dashboards
to - AI helping people ask, analyze, generate, push, alert, and follow up
Dora should not be viewed as a generic chatbot or as a replacement for FineBI. It is better understood as an enterprise Data Agent and part of an Agentic BI workflow.
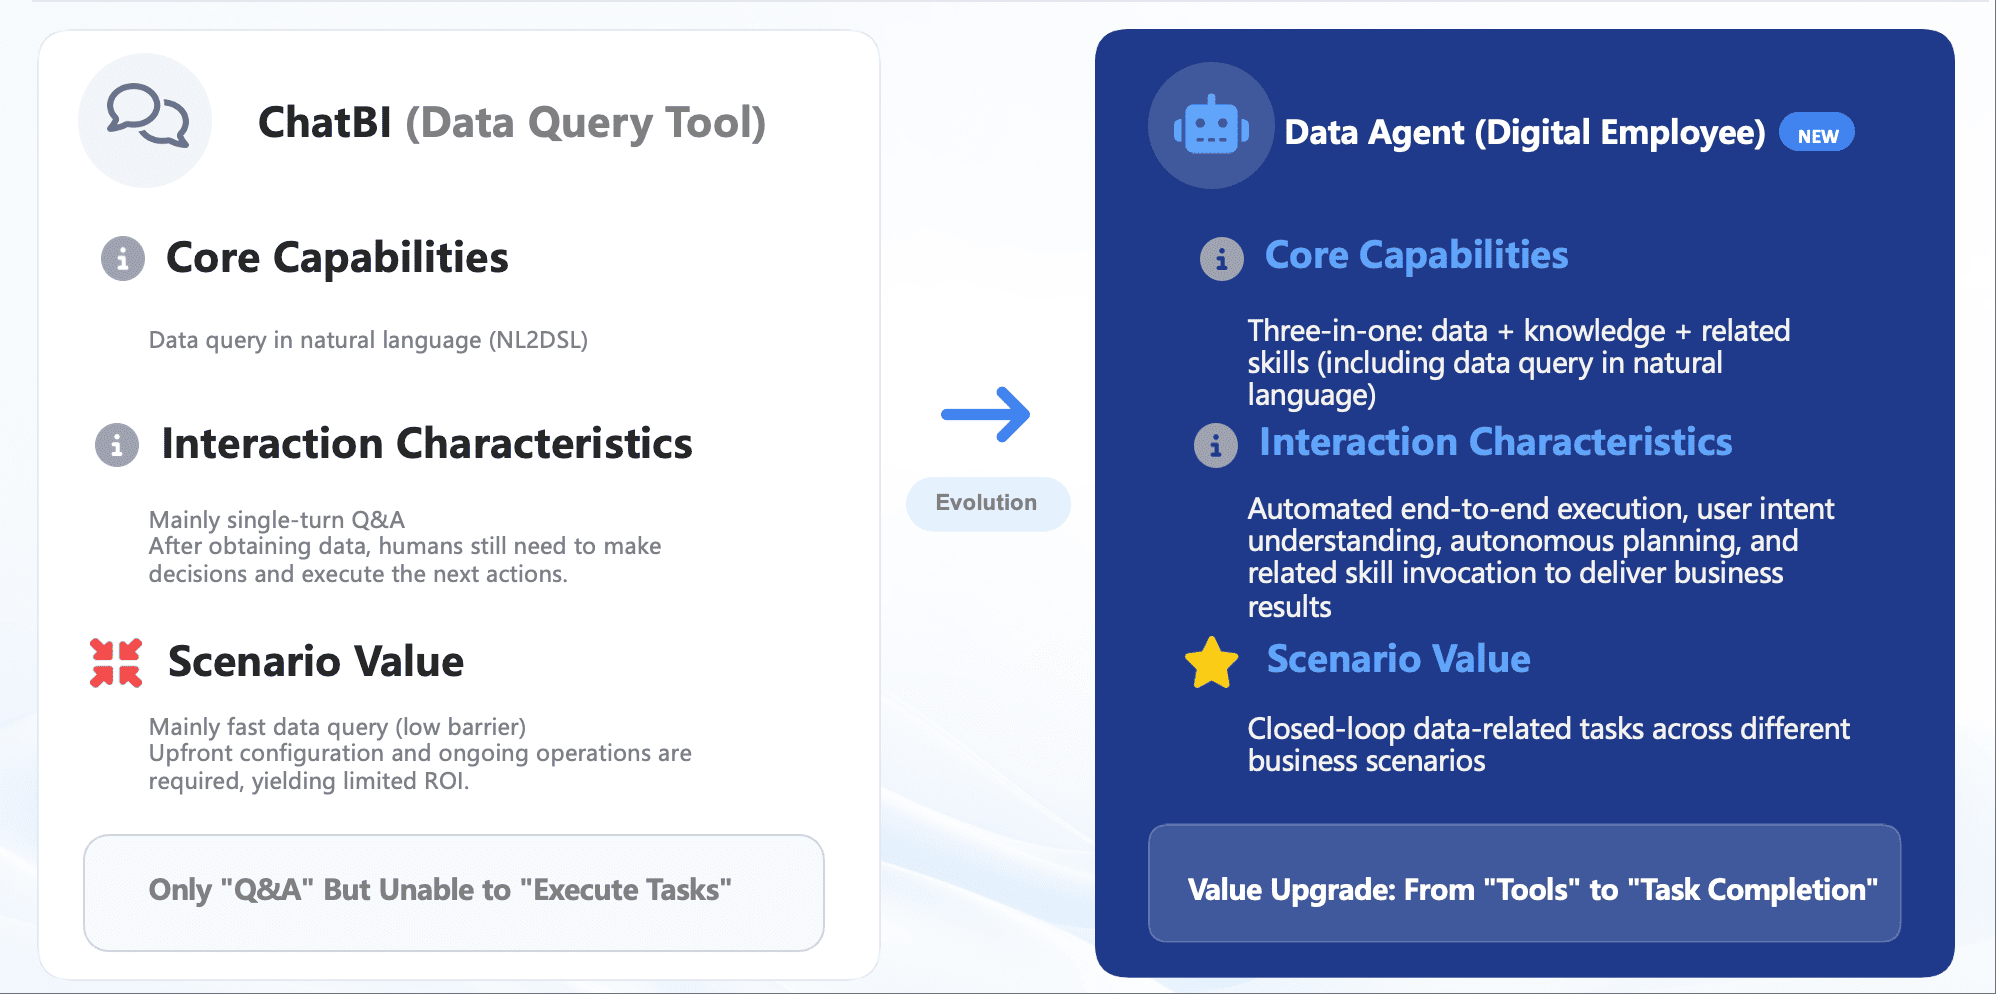
That means a user can move through a governed process such as:
- natural-language request
- trusted semantic understanding
- governed query or skill execution
- answer, chart, summary, action, and follow-up
This is useful in scenarios such as:
- Data Analyst digital employee for recurring analytical questions
- Report Researcher for automated metric lookups and summaries
- Daily Briefing Secretary for scheduled business updates
- Risk Alert Officer for proactive anomaly and issue follow-up
For enterprises comparing Databricks competitors, this matters because the evaluation should not stop at data storage or processing. The bigger question is how people across the organization actually interact with data and decisions.
Get Ready-to-Use Dashboard Templates in Fine Gallery
Final takeaway
The best Databricks competitors in 2026 depend on what you are really buying for.
- Choose Snowflake, BigQuery, or Redshift if warehouse-centered analytics is your top priority.
- Choose Fivetran, Informatica, or Talend if your biggest issue is ETL and integration operations.
- Choose Confluent, Flink-based platforms, or RisingWave if real-time streaming is the main workload.
- Choose Snowpark-based stacks or Microsoft Fabric if your team needs a different path to collaborative analytics and AI.
- Choose FineBI first if your gap is self-service BI, interactive dashboards, and broader business adoption of data.
And if your organization wants to go beyond dashboards into governed AI-assisted analysis, FineBI + Dora is worth shortlisting as a modern combination of self-service BI plus enterprise Data Agent capability.
FAQs
Databricks competitors usually fall into four groups: BI platforms, cloud data warehouses, ETL and data integration tools, and streaming or ML platforms. The best alternative depends on whether your main need is dashboards, SQL analytics, pipeline automation, real-time data, or machine learning.